Asset Ranking for Multi-Manager Funds
A conventional rank sorts a group on one statistic. Return, Sharpe ratio, maximum drawdown and VaR each answer a different question, and each discards the others. A fund can lead a hedge-fund peer set on Sharpe and sit near the bottom on drawdown. A long-only manager can lead on annualized return with a beta the allocation cannot hold. The sort is not wrong. It is a rank on one number, and manager selection for a fund of funds is rarely a decision on one number.
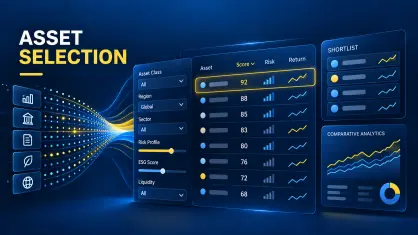
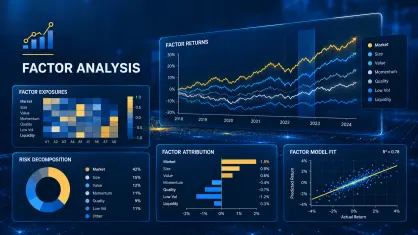
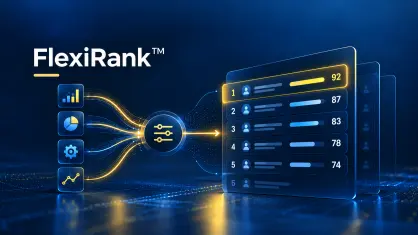
Risk Shell FlexiRank™, introduced in 2007 as a Quant Suite component for hedge fund ranking, addresses this problem by allowing users to create their own ranking criteria from multiple risk and performance measures. Each underlying statistic can be assigned a user-defined importance, producing a composite or synthetic risk metric that reflects the investor's own priorities. The user selects the constituent measures — drawdown, VaR, volatility, Sortino, Omega, alpha, beta, or any other risk statistic in the set — and assigns an importance level to each. The group is then ranked on the combined result. The importance levels are the investment view: a credit-sensitive book can put more weight on drawdown and tail loss than on headline return; a market-neutral allocation can put more weight on beta and correlation than on absolute performance. Changing the weights changes the rank. It does not require a different data set.
The synthetic metric also deals with a practical defect of any single hedge-fund statistic. Sharpe penalises upside volatility and is unstable on short, non-normal series. A drawdown rank says nothing about the return earned for that loss. Calmar and Sortino each repair one of those gaps and open another. A weighted combination does not make the constituents valid. It stops the selection from being decided by whichever single defect the sort happened to use.
The same rank runs on hedge funds, traditional long-only funds, equities, CTAs and multi-asset portfolios, and on a group drawn from more than one data set. Presets store a specification — constituents and importance levels — so a ranking used in manager selection can be reapplied to the next universe without being rebuilt. The number of combinations is large because both the choice of constituents and the weights are open. A stored preset is what makes a complex specification repeatable.